What text recognition does
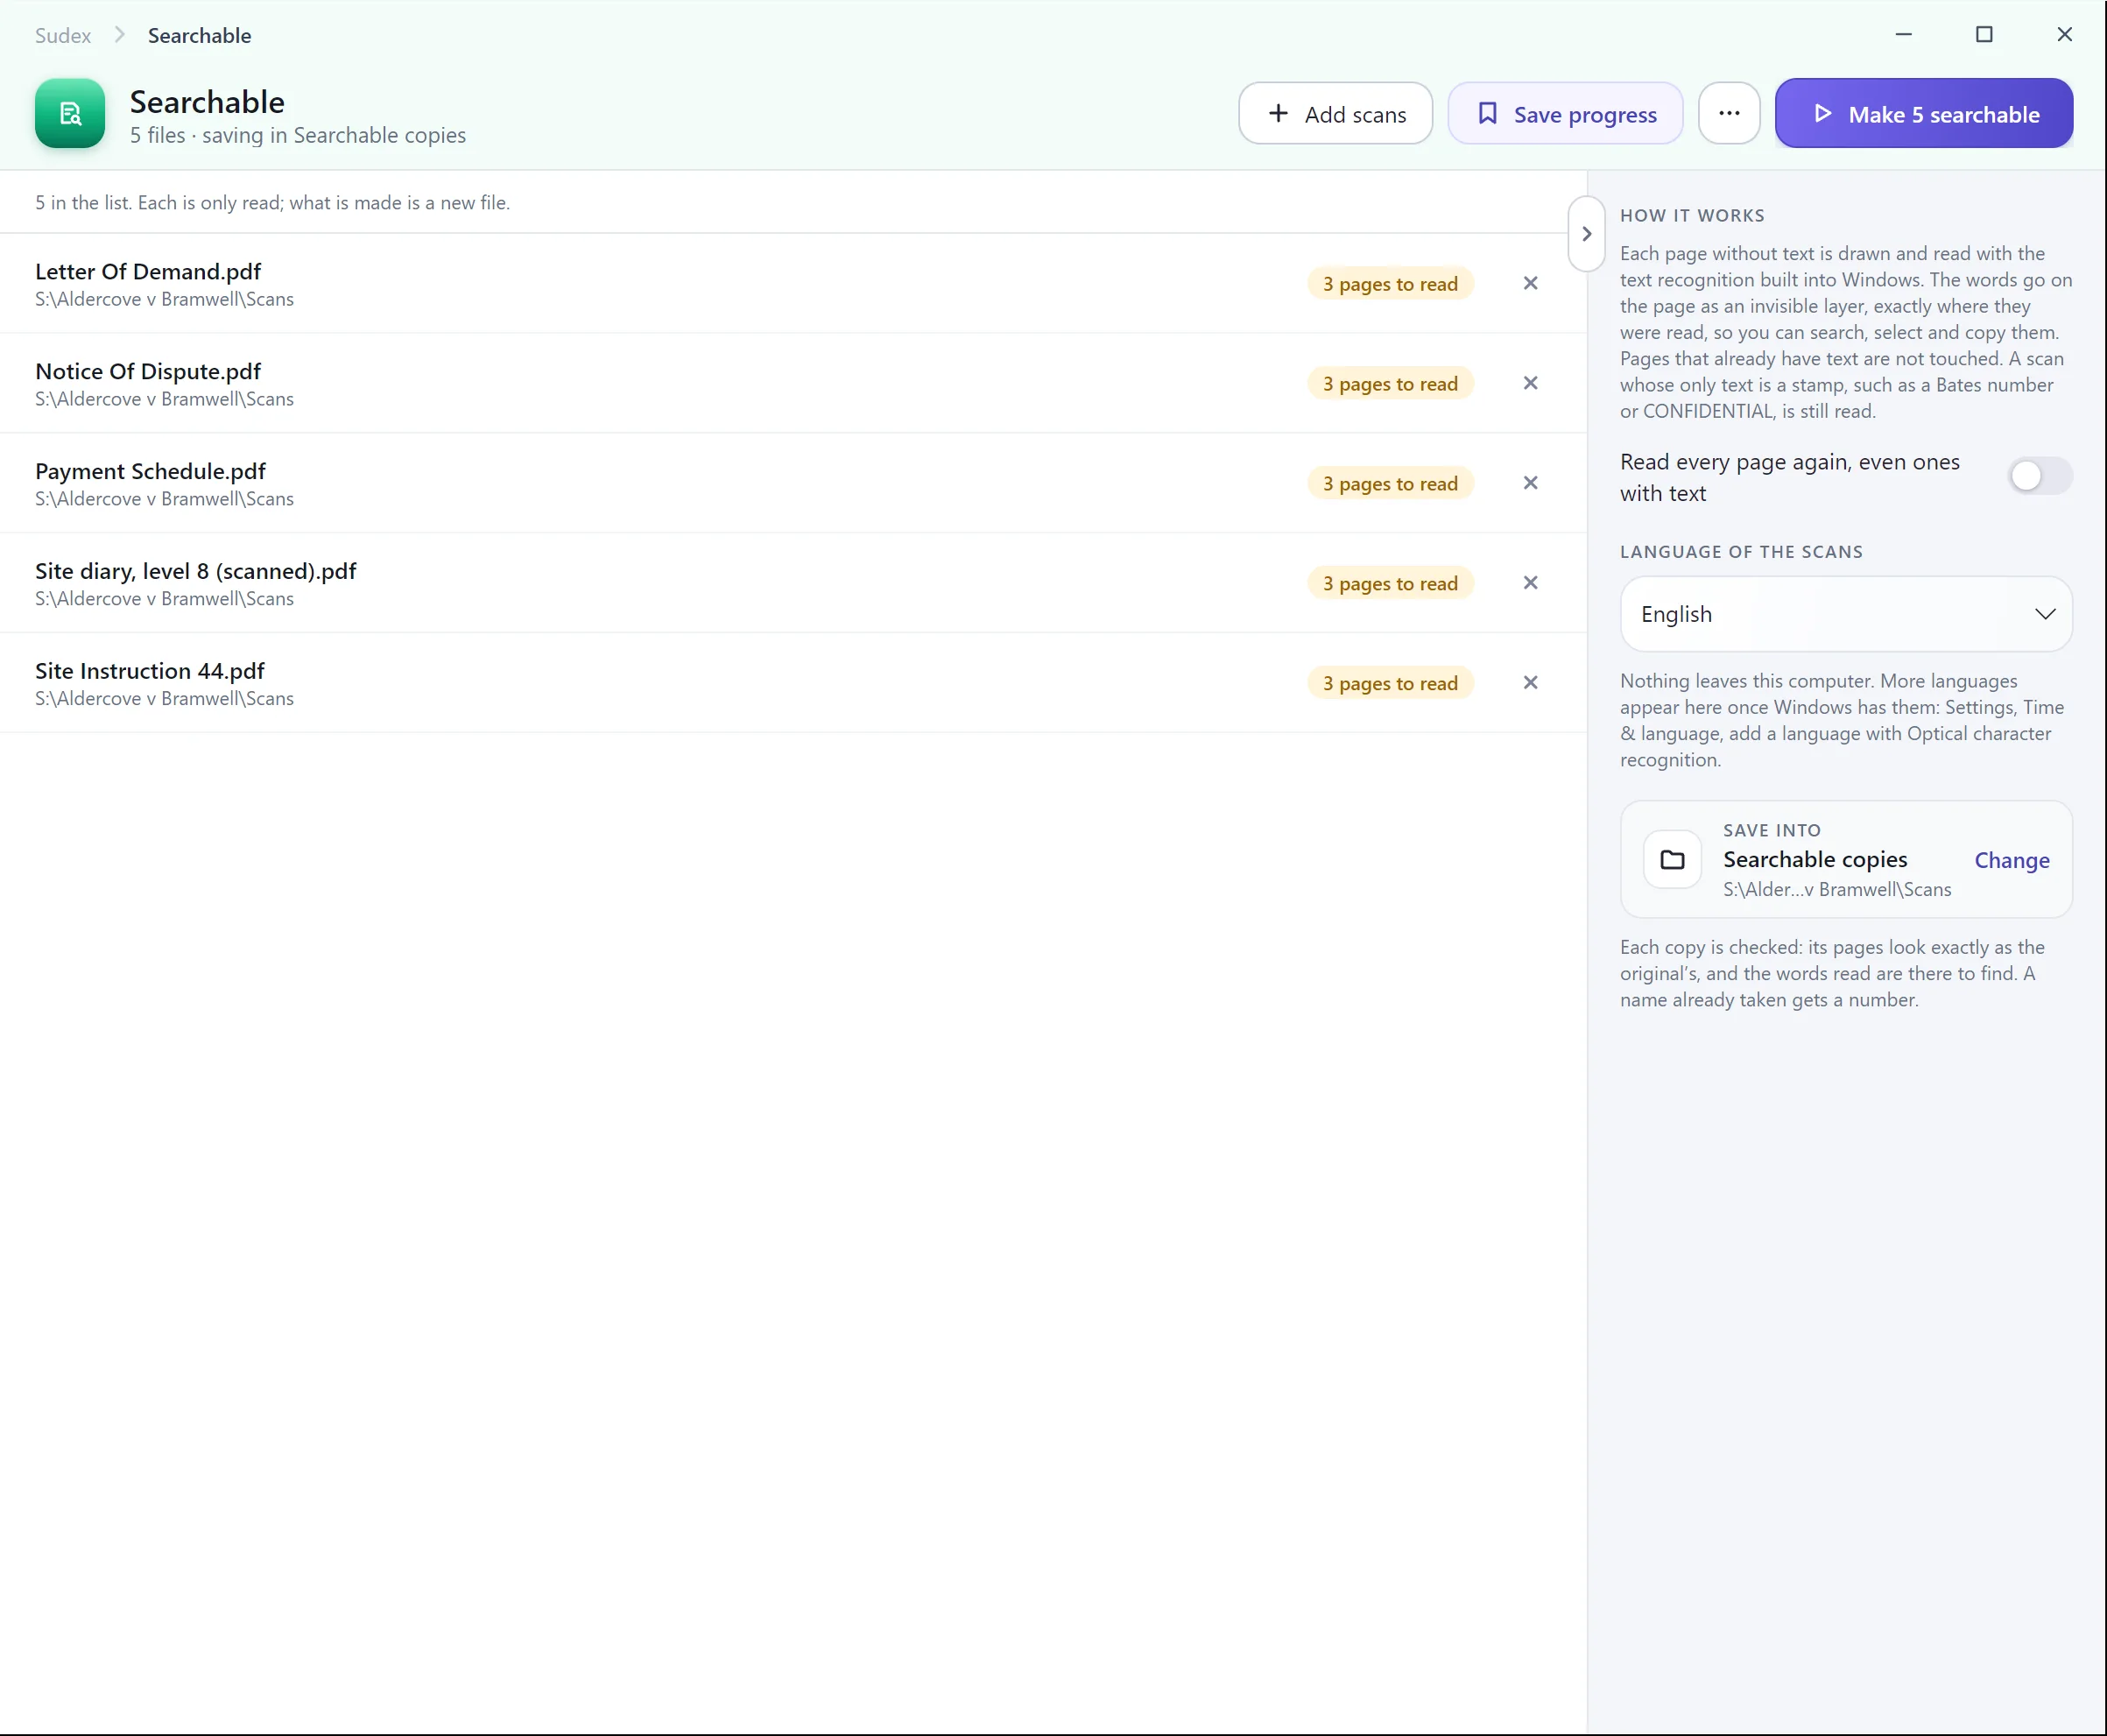
When a paper document is scanned, the PDF holds a picture of each page and no words at all. Text recognition, often called OCR (optical character recognition), reads the letters in each picture and adds the words to the page as an invisible layer, in the places they appear. The page looks exactly as before, but you can now search it, select a passage and copy it.
Why courts ask for it
Electronic bundles are expected to be searchable. The judiciary’s general guidance for England and Wales asks for scanned pages with typed text to go through OCR so they can be searched, highlighted and copied. The Federal Court of Australia asks for the text on every page of an eBook or appeal book to be searchable and able to be copied: see our guides to eBooks and appeal books. Even where a court doesn’t ask, a searchable bundle saves time for everyone using it.
Why do it offline
Many free OCR tools are websites: you upload the scan, and download a searchable copy. That sends the document to someone else’s computer. For client documents, privileged material or anything under a confidentiality order, check your firm’s policy before using one. Software that reads the pages on your own computer avoids the question. If you use a desktop program, check that its text recognition runs on the computer rather than through an online service, and where it saves the result.
1. Check whether it already has text
Open the PDF and search (Ctrl+F) for a word you can see on the page, or try to select a line of text. If the search finds nothing, or the whole page selects as one picture, the page has no text yet. A file can be mixed: typed pages with text, and scanned pages without it, such as a signed page or an annexure.
2. Keep the original and prepare the scan
- Work on a copy, and keep the original scan as it was.
- Turn sideways or upside-down pages the right way up first. Text recognition reads them poorly, if at all.
- Note the language of the document, since the program needs to know it to read accented letters properly.
- If you are scanning, scan clearly, straight and at a sensible resolution. The UK general guidance says an e-bundle’s resolution should be no greater than 300 dpi, to avoid slow scrolling.
3. Run text recognition
In Adobe Acrobat, Adobe’s help on recognising text in scanned documents gives these steps, and menu names change between versions:
- Open the scanned PDF and select All tools, then Scan & OCR.
- Select In this file.
- Choose the page range and the language, and any other settings.
- Select Recognize Text, then save the file.
For several files, choose In multiple files instead, add the PDFs and choose a folder for the searchable copies.
Without Acrobat, other desktop PDF editors have their own text recognition. If you are comfortable with the command line, OCRmyPDF is open-source software that adds a text layer to scanned PDFs using the Tesseract engine, and supports Windows, macOS and Linux.
4. Check the result
- Search for a few words from different pages, including names and numbers, and check they are found.
- Check every page was read: a blank, faint or handwritten page may have no text, and a page read the wrong way up may have nonsense.
- Check the pages still look exactly as they did. Some programs offer to “clean up” or reflow a scan, which changes how it looks; for evidence, the page should stay as it was scanned.
- Check the page count matches the original.
Text recognition is rarely perfect. A search that finds nothing doesn’t prove a word isn’t there, so don’t rely on it alone for anything important.
With Sudex